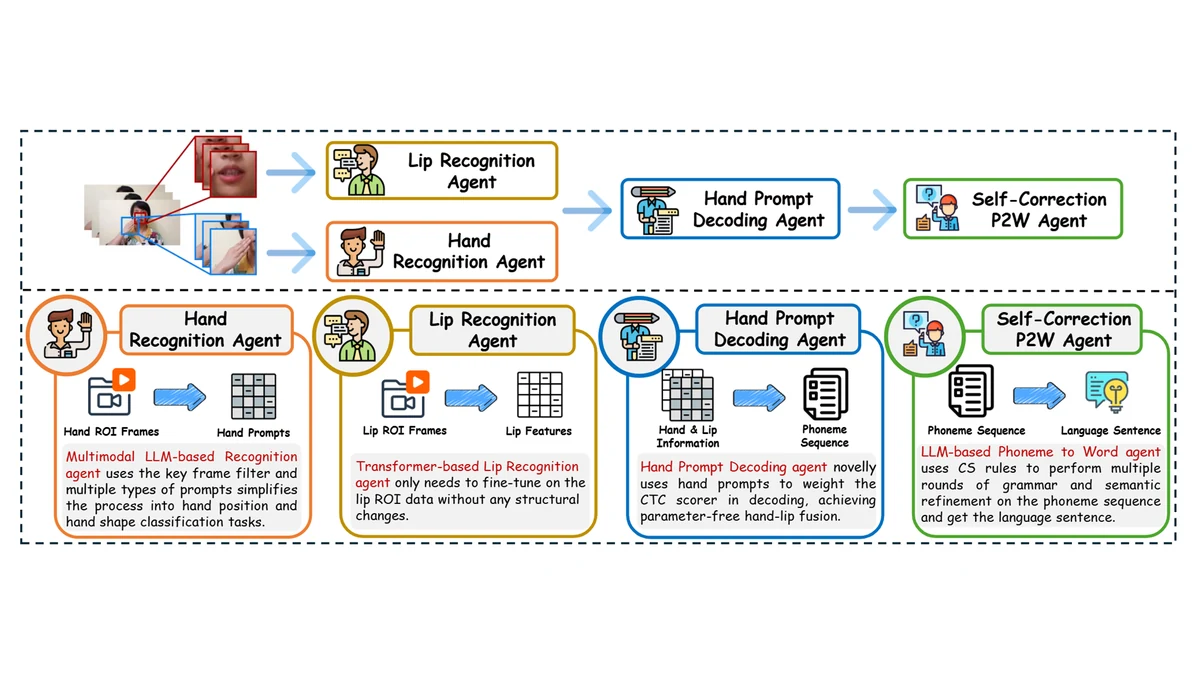
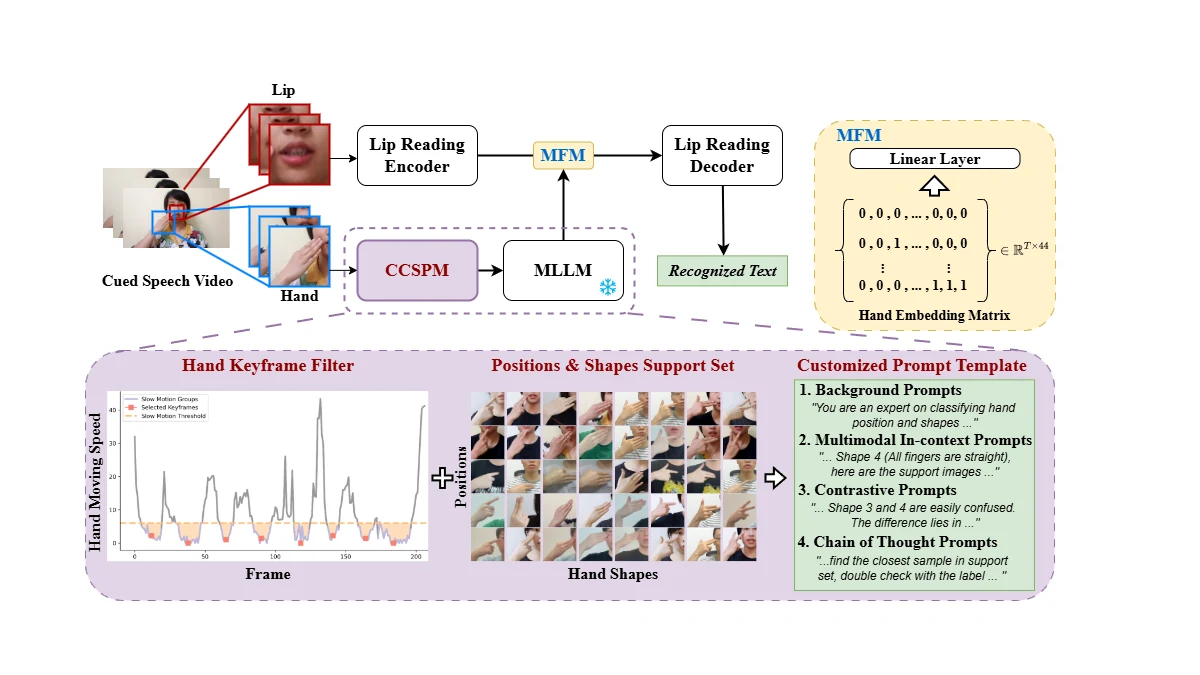
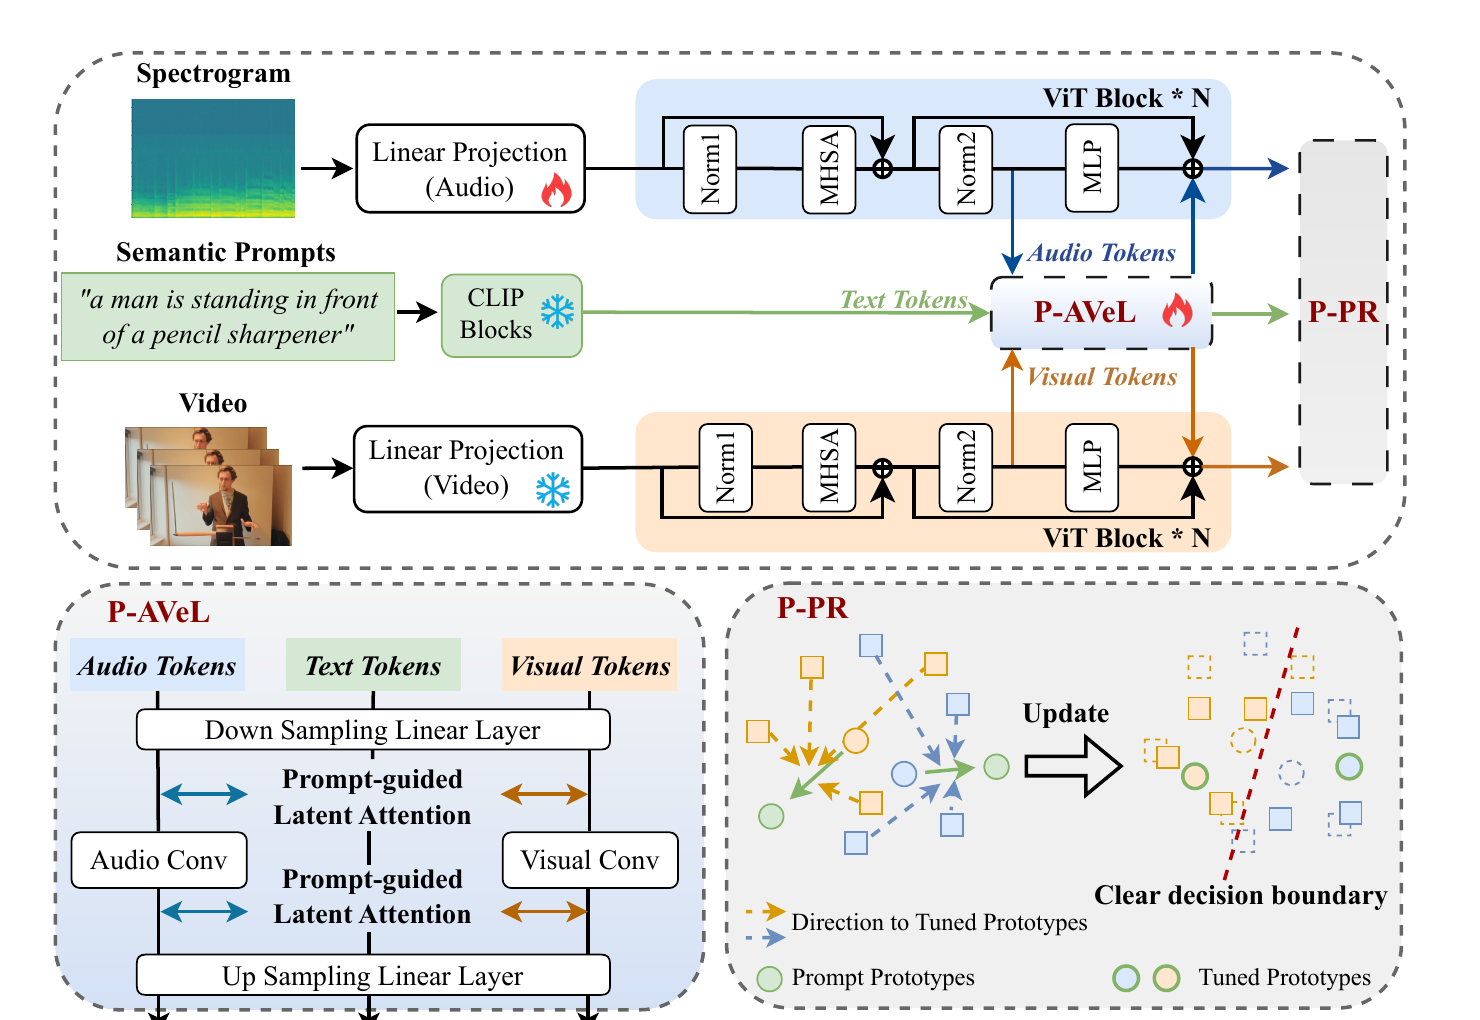
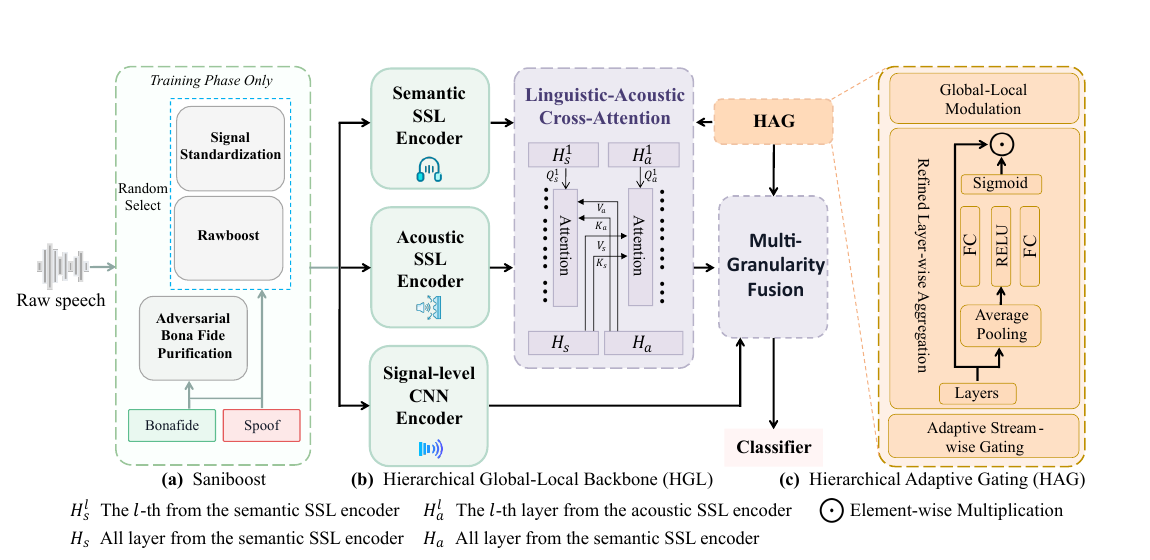
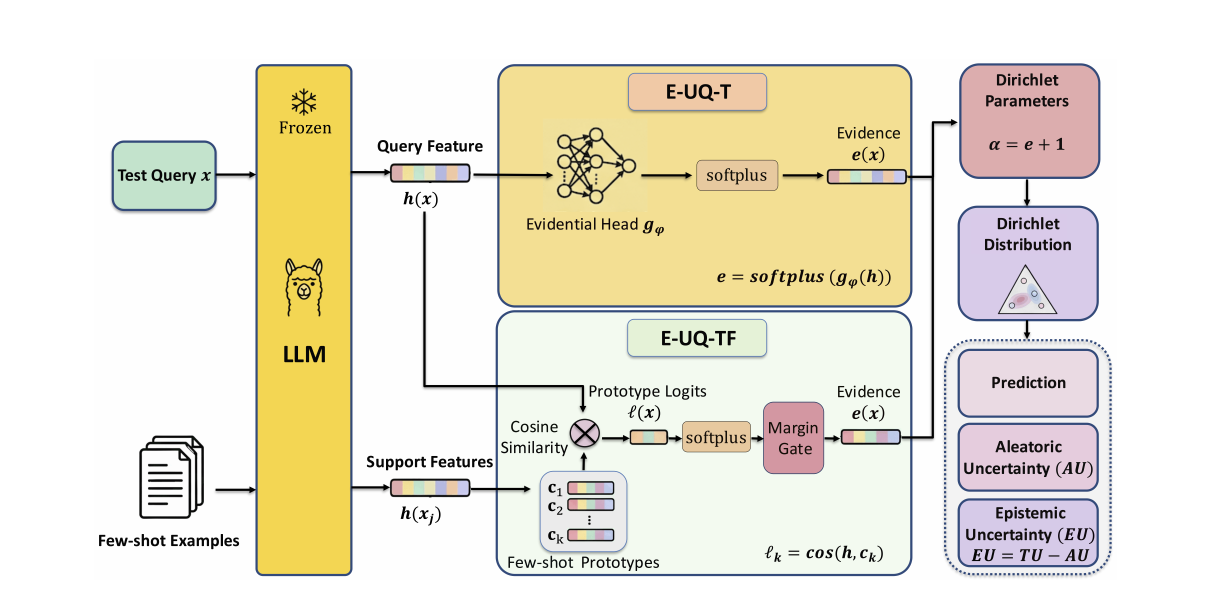
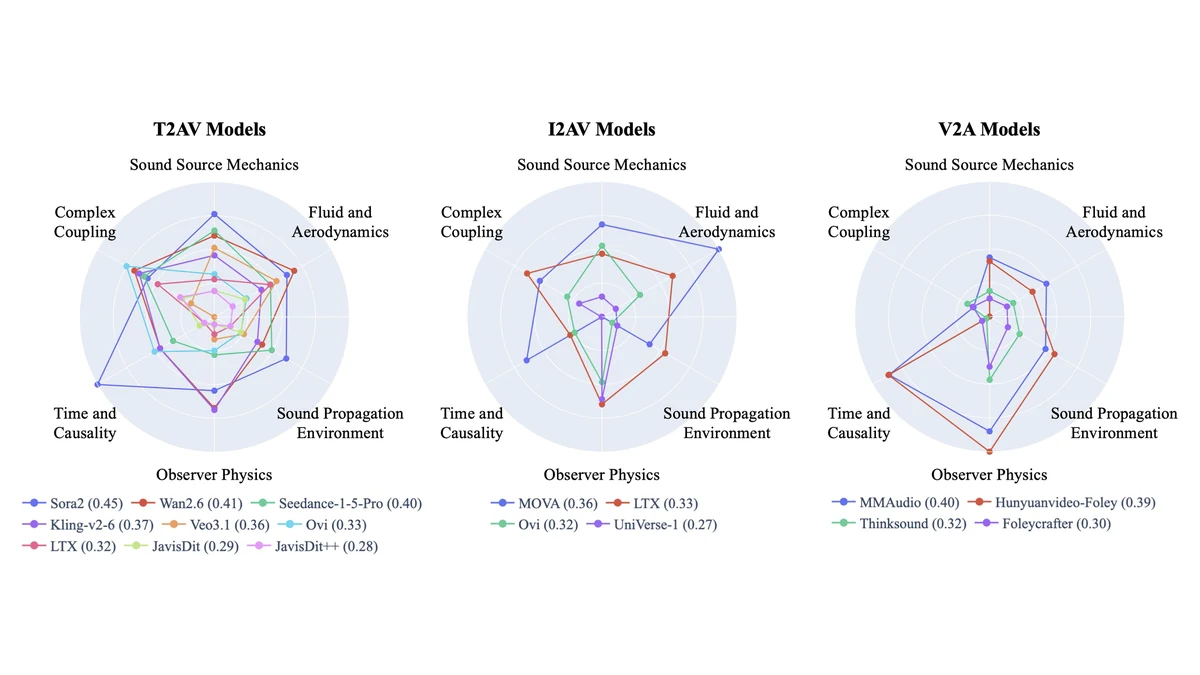
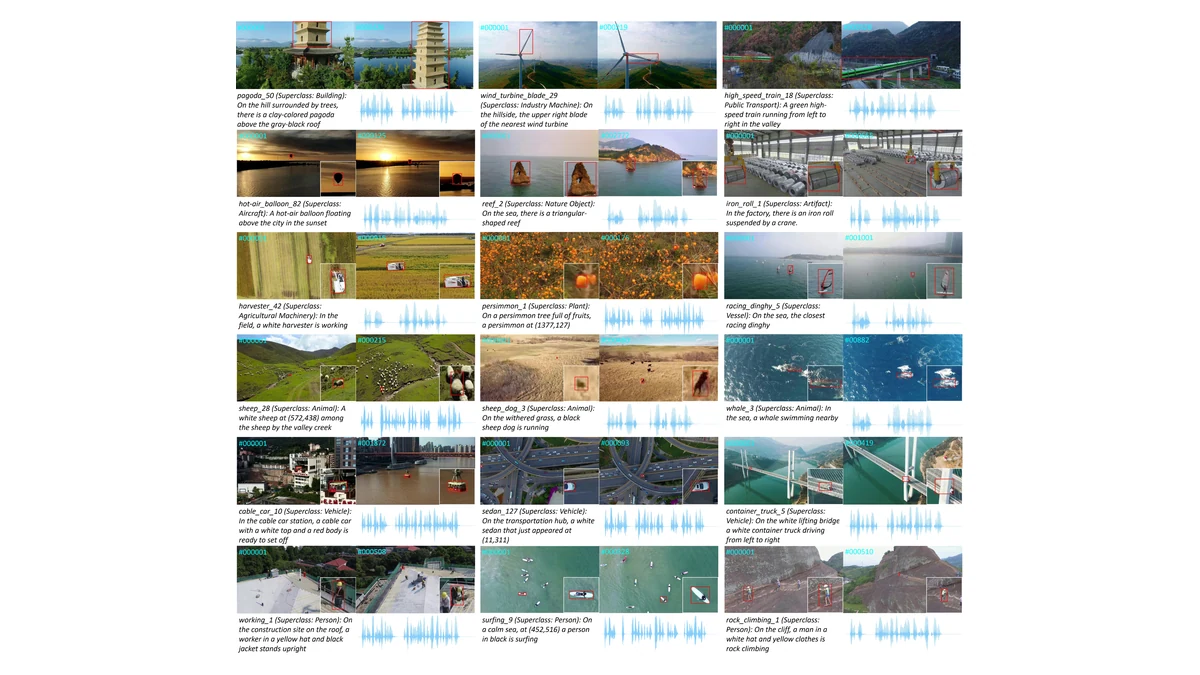
Research Cued-Agent Four specialized agents connect hand-cue recognition, lip reading, prompt-based decoding, and language-level self-correction. STF-ACSR An MLLM recognizes informative hand cues without task-specific training, and a single linear layer injects them into a lip-reading model. Semantic Modulated Prompting Semantic prompts align asynchronous audio-visual evidence and dynamically rebalance weak modalities in few-shot learning. GLAD: Audio Deepfake Detection Global-local SSL features, sample-adaptive gating, and SaniBoost improve detection under unseen attacks and domain shifts. Evidential Uncertainty for In-Context Learning Single-pass, query-level evidential uncertainty reduces prompt dependence and the token cost of reliable in-context learning. Benchmark PhyAVBench Controlled prompt pairs test whether generated sound changes correctly when one underlying physical condition changes. WebUAV-3M A 3.3M-frame UAV tracking benchmark with dense boxes, language specifications, audio descriptions, and diverse target categories.