STF-ACSR
An MLLM recognizes informative hand cues without task-specific training, and a single linear layer injects them into a lip-reading model.
STF-ACSR reframes continuous hand modeling as a zero-shot MLLM classification task, then uses minimalist fusion to prompt a pretrained lip-reading model. This design reduces overfitting in low-data automatic cued speech recognition.
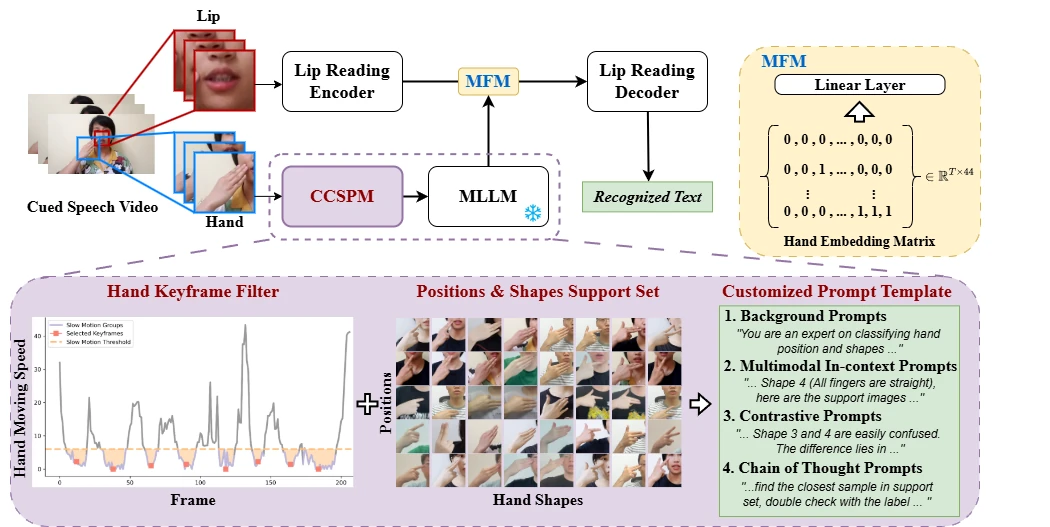
The STF-ACSR framework from the paper and official project repository.
Core highlights
- Training-free hand prompting: a motion-based filter selects keyframes, while background, multimodal context, contrastive, and reasoning prompts activate the MLLM’s hand-cue recognition ability.
- Minimalist fusion: recognized cues are converted into an embedding matrix, aligned by one linear layer, and added to lip features as prompts.
- Designed for scarce data: the method avoids training a complex temporal hand model or a large fusion network while preserving complementary hand and lip information.
The work was accepted at ICASSP 2026.