WebUAV-3M
A 3.3M-frame UAV tracking benchmark with dense boxes, language specifications, audio descriptions, and diverse target categories.
WebUAV-3M addresses the limited scale, modality coverage, and scene diversity of earlier UAV tracking datasets through a million-scale multimodal benchmark.
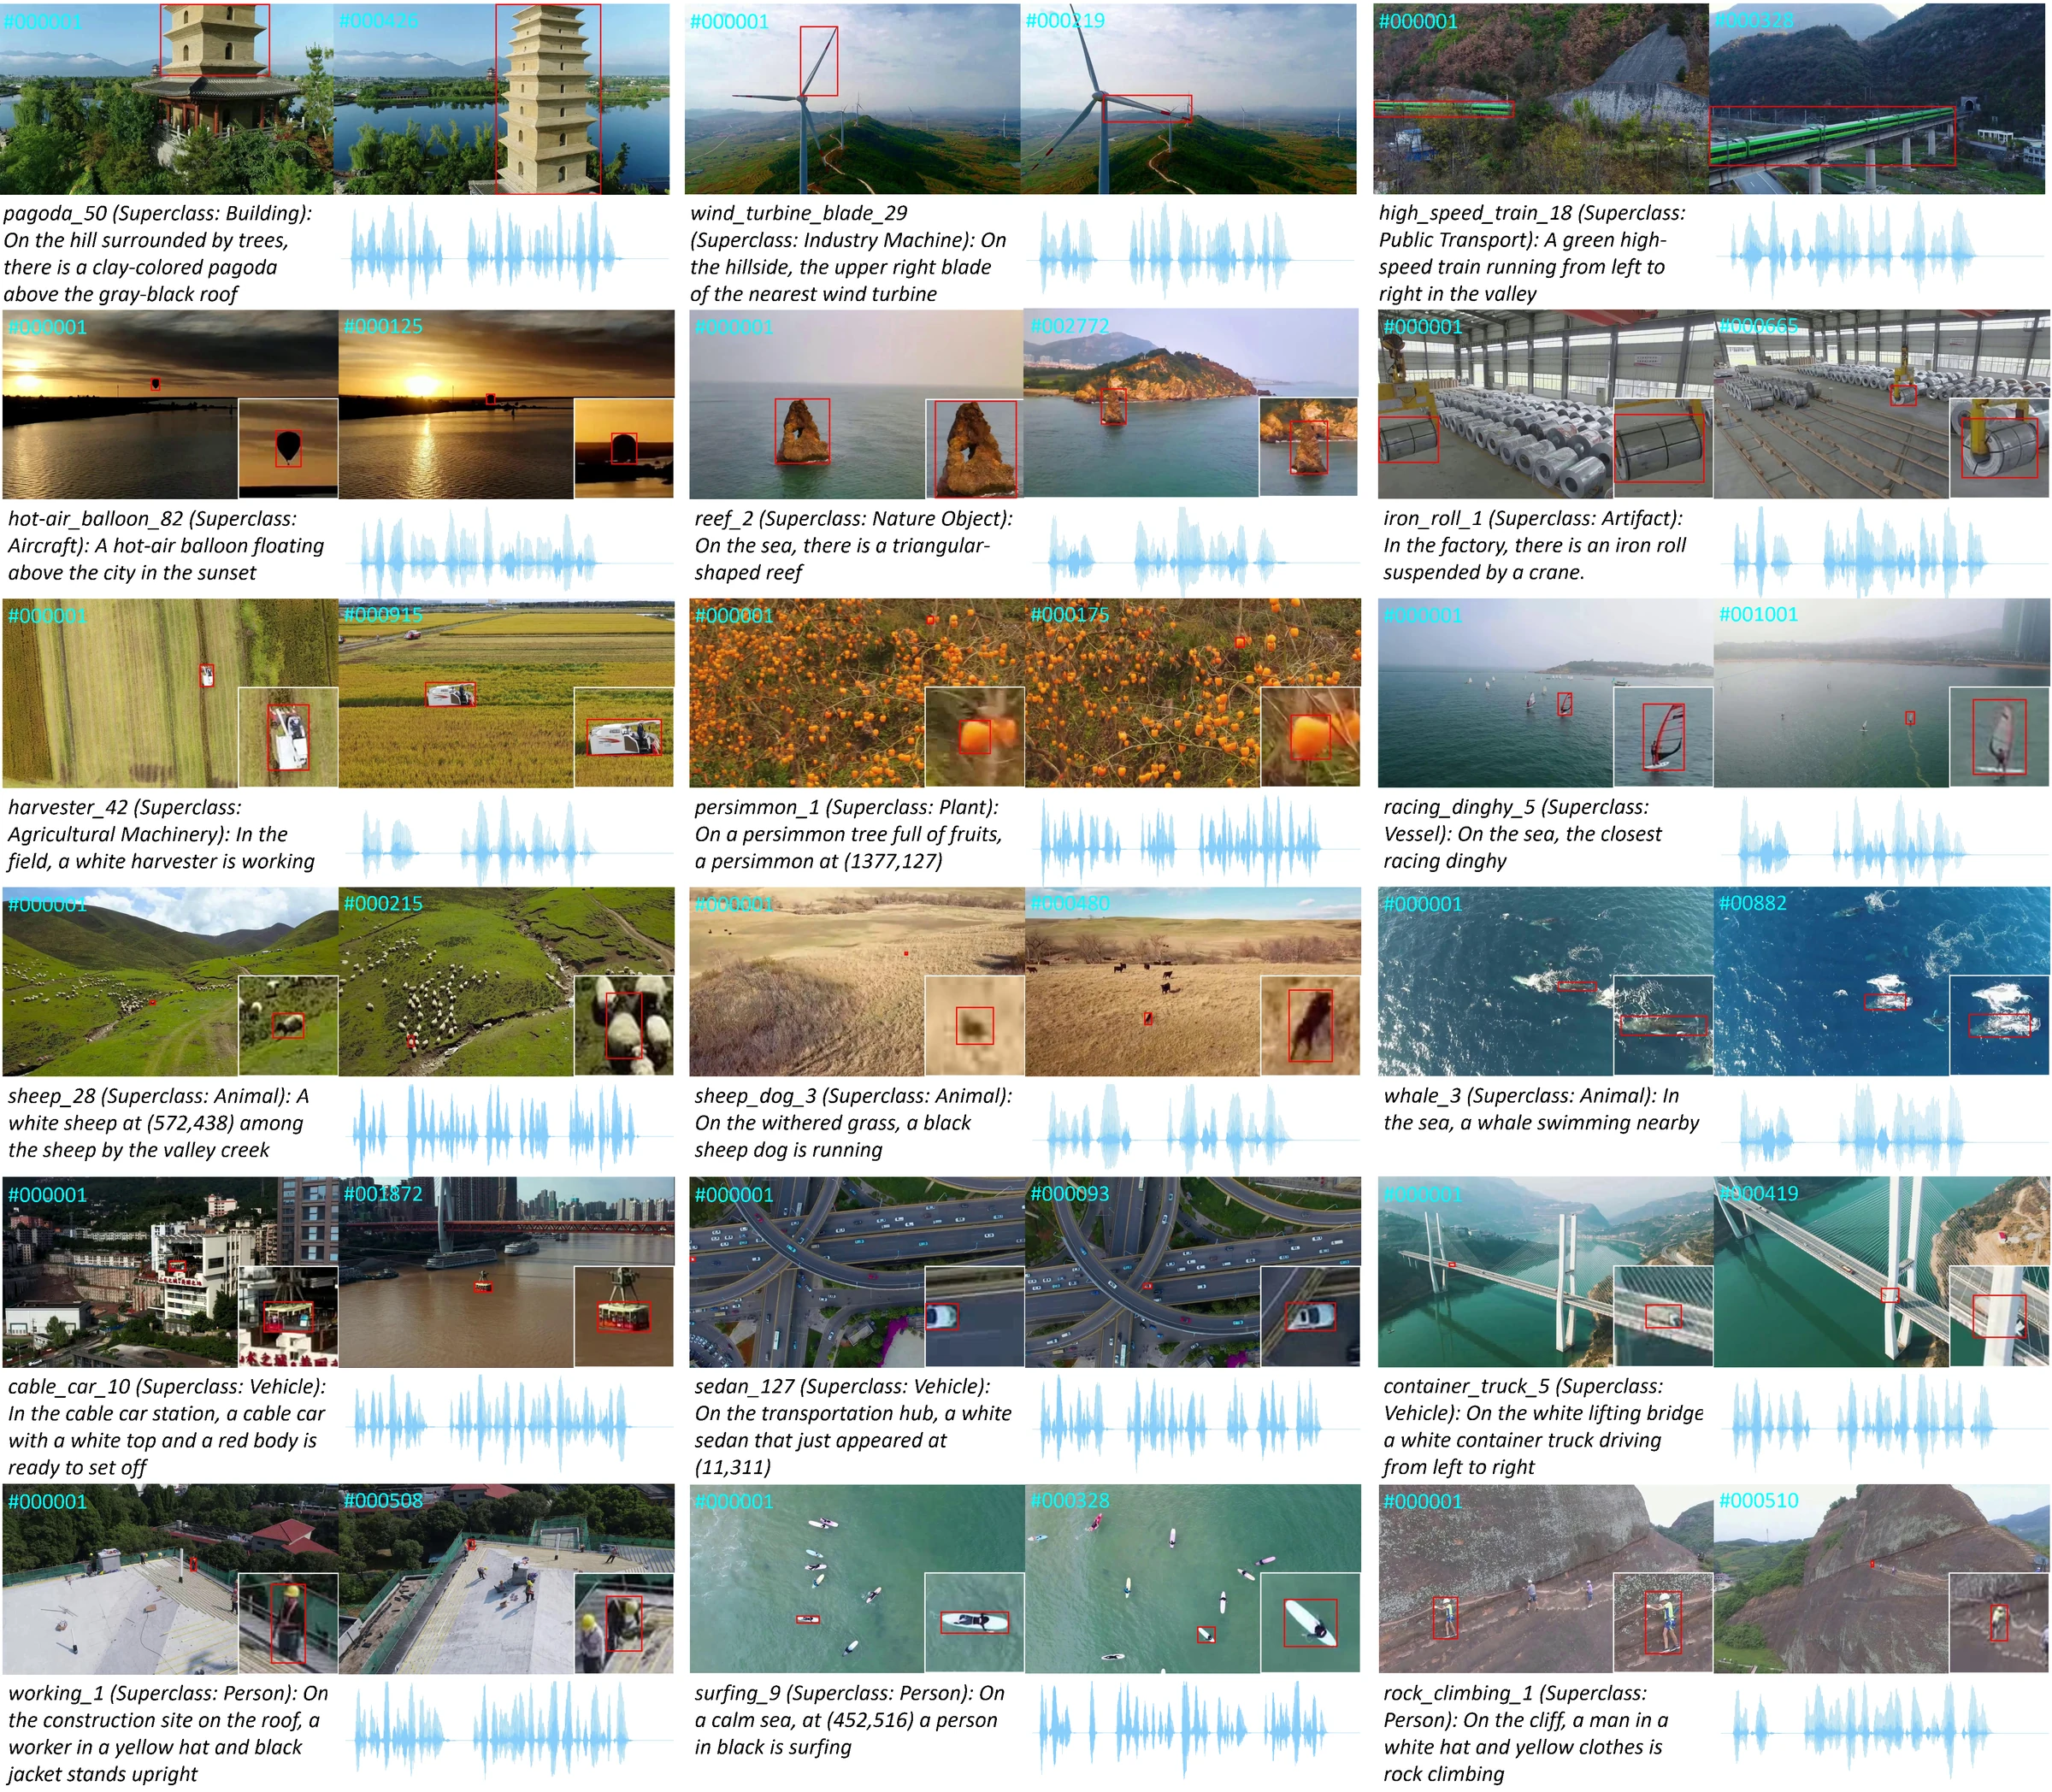
Representative videos, target boxes, language specifications, and audio waveforms from the paper and official repository.
Core highlights
- Million-scale coverage: 3.3 million frames from 4,500 video sequences across 223 target categories, including buildings, vehicles, animals, people, and industrial objects.
- Multimodal annotations: dense boxes are complemented by natural-language specifications and audio descriptions to reduce ambiguity during occlusion, appearance changes, and long-term tracking.
- Fine-grained evaluation: seven scenario-constrained subsets and a unified comparison of more than 40 representative trackers.
- Scalable construction: a semi-automatic annotation pipeline made dense labeling at this scale practical.
I contributed as a co-first author and helped build the dataset tooling and multimodal benchmark. The work was published in IEEE Transactions on Pattern Analysis and Machine Intelligence.