Cued-Agent
Four specialized agents connect hand-cue recognition, lip reading, prompt-based decoding, and language-level self-correction.
Cued-Agent addresses hand-lip asynchrony, limited training data, and the gap between phoneme recognition and natural-language output by dividing the full automatic cued speech recognition pipeline among four specialized agents.
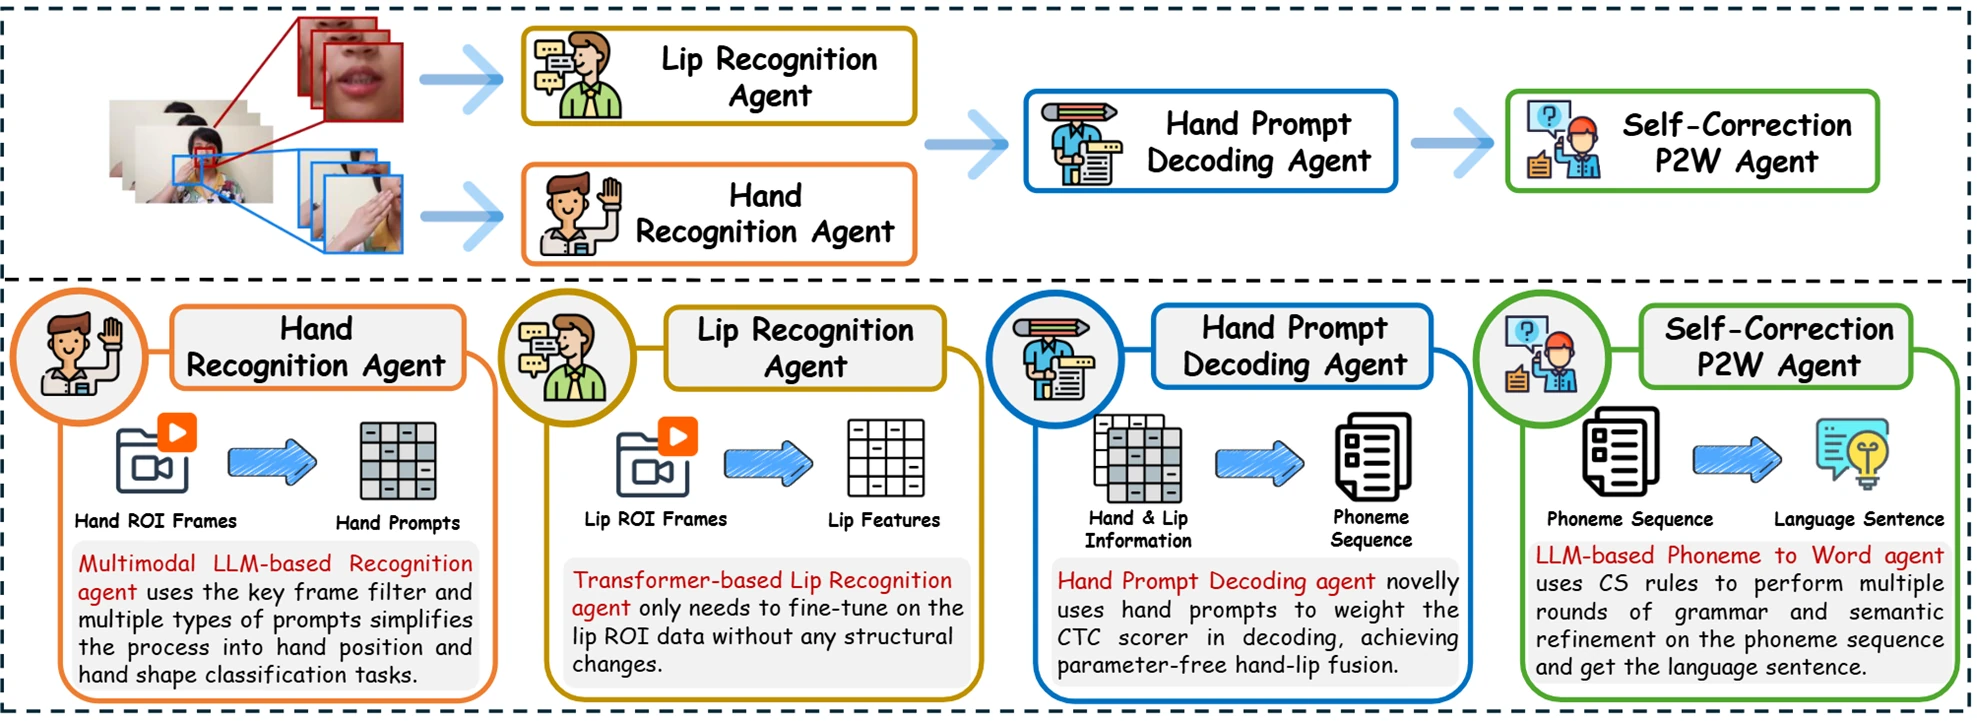
The four-agent framework from the paper and official project repository.
Core highlights
- Four-agent collaboration: hand recognition, lip recognition, hand-prompt decoding, and phoneme-to-word self-correction cover perception, multimodal fusion, and language generation.
- Minimal training overhead: an MLLM recognizes hand cues from selected keyframes, while parameter-free score fusion injects the cues into lip-reading decoding.
- Language-level correction: an LLM uses cued-speech rules to refine phoneme sequences and produce natural sentences.
-
Real-world data: the project includes a Mandarin cued speech dataset collected with speakers who have hearing impairment. The paper was selected for an ACM Multimedia 2025 oral presentation and received a Student Travel Award.
- Paper
- Code and data